Super-Resolution图像/视频超分
Super-Resolution图像/视频超分
数据预处理
降质方法(Degradation)
- Residual Dense Network for Image Super-Resolution
- resize by bicubic
- Gaussian Blur kernel 7x7
- Gaussian Noise level 30
- Old Photo Restoration via Deep Latent Space Translation
- Gaussian white noise with (5, 50)
- Gaussian blur with kernel size (3, 5, 7) and standard deviation (1,0, 5.0)
- JPEG compression whose quality level in the range of (40; 100);
- Color jitter which randomly shifts the RGB color channels by (-20; 20);
- Box blur to mimic the lens defocus
数据增强(Data augmentation)
-
flip: flipping horizontally or vertically
-
rotating旋转: 90 180 270
-
batch-size: 16
-
image size: 48x48 / 32x32
-
adam: init lr: 10-4, after 200 epoch: 5x10⁻⁵
-
mini-batch size of SGD to 64, momentum parameter to 0.9, and weight decay 10-4
评价指标
PSNR
SSIM
LPIPS
FID
数据集
-
training set: DIV2K dataset
-
standard benchmark testing datasets
- Set5
- Set14
- B100
- Urban100
- Manga109
-
Learning deep cnn denoiser prior for image restoration
-
Spatial pyramid pooling in deep convolutional networks for visual recognition
-
L. Zhu, “pytorch-opcounter,” https://github.com/Lyken17/ pytorch-OpCounter, 2019.
经典算法
EDSR:Enhanced Deep Residual Networks for Single Image Super-Resolution
RDN:Residual Dense Network for Image Super-Resolution
意图
Residual learning + Densnet
网络结构设计
全局残差学习
所有RDB的全局fusion(GFF)
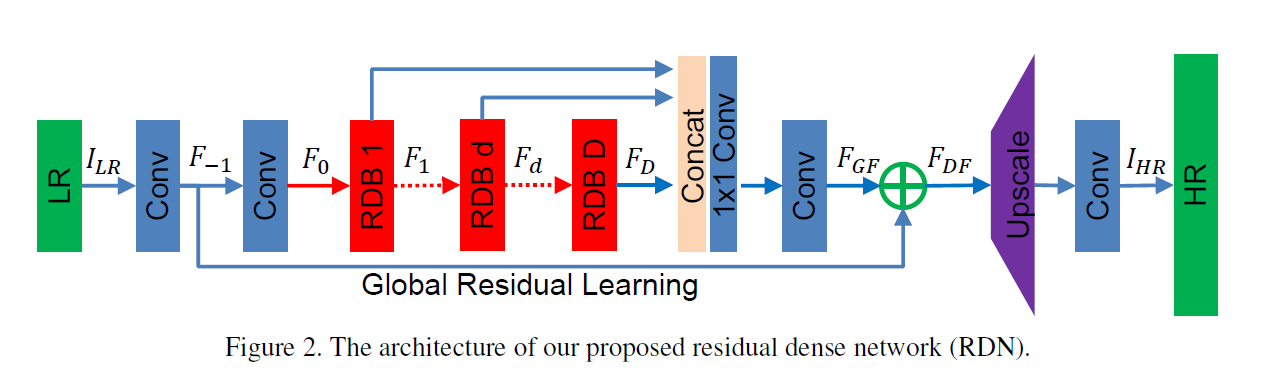
- RDB: 20个
RDB: residual Block + dense Block
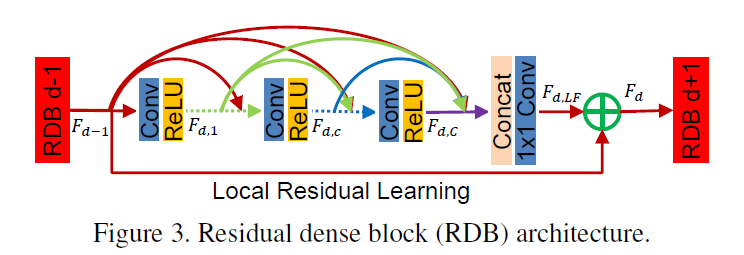
- RDB中conv: 6个
- Densnet Grow rate: 32
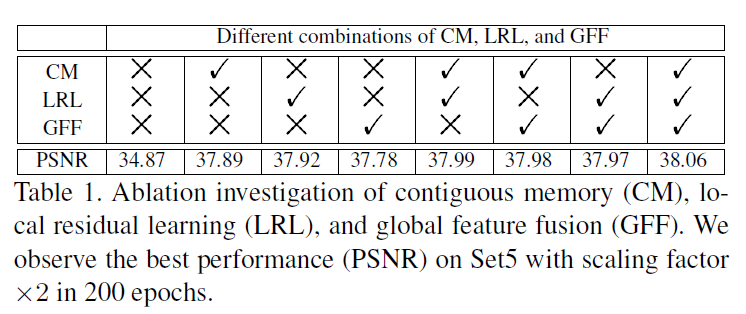
不同结构的比较
CM的只是dense connection(Densnet)
训练
- flip: flipping horizontally or vertically
- rotating旋转: 90 180 270
- batch-size: 16
- image size: 48x48 / 32x32
- adam: init lr: 10-4, after 200 epoch: 5x10⁻⁵
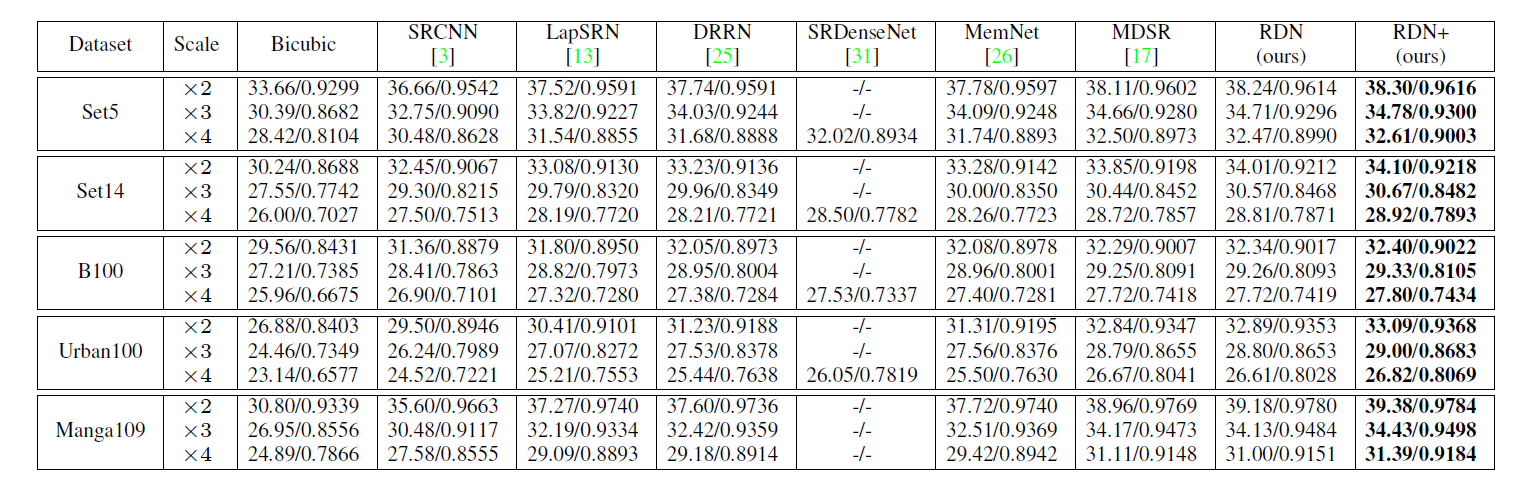
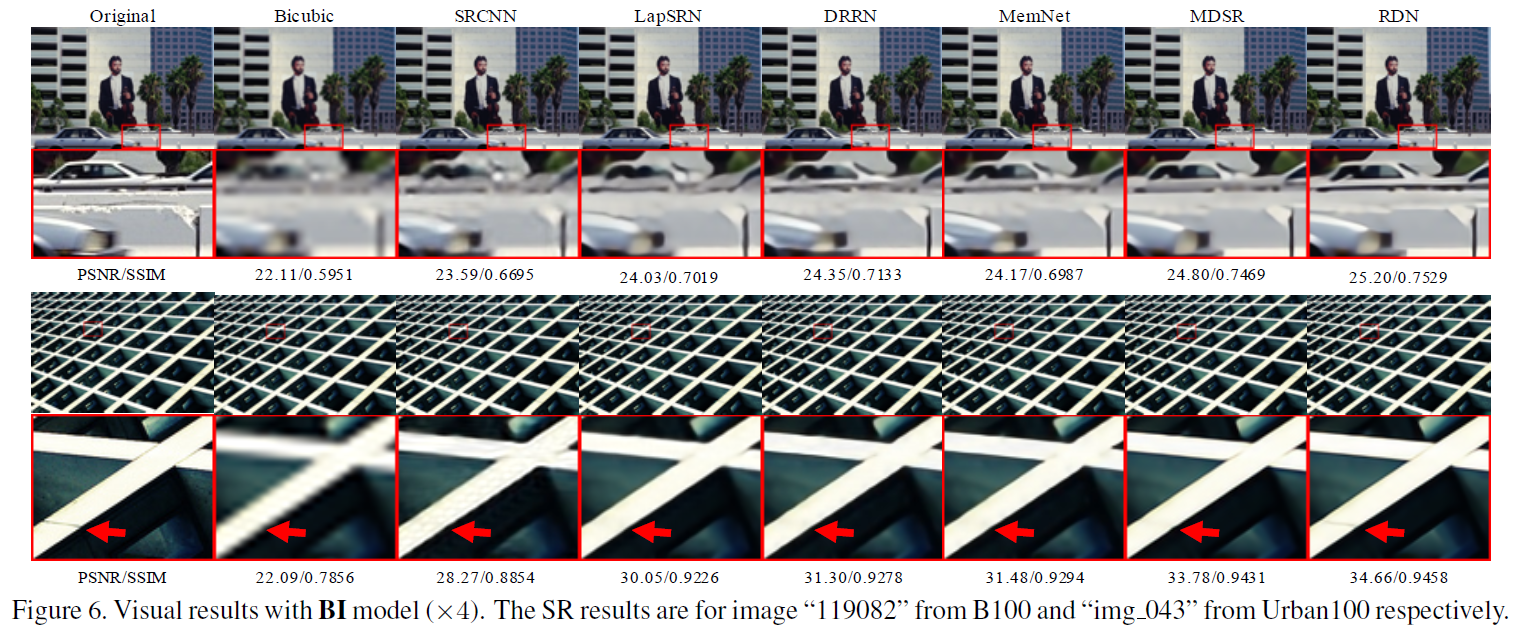
结果
RCAN:Image Super-Resolution Using Very Deep Residual Channel Attention Networks
意图
EDSR通过构建深度的残差模块获得显著的SR性能的提升,意图引入有效利用channel-wise features来构建有效的深度SR模型。
- high-frequency channel-wise features are more informative for HR reconstruction.
- It also indicates that deeper networks may be easier to achieve better performance than wider networks.
网络结构设计
CA channel attention
LR中有冗余的低频信息和有价值的高频信息,如边缘,纹理和其他细节。 利用attention来甄别信息权重。 CA基本和SE-Net的注意力机制一样。
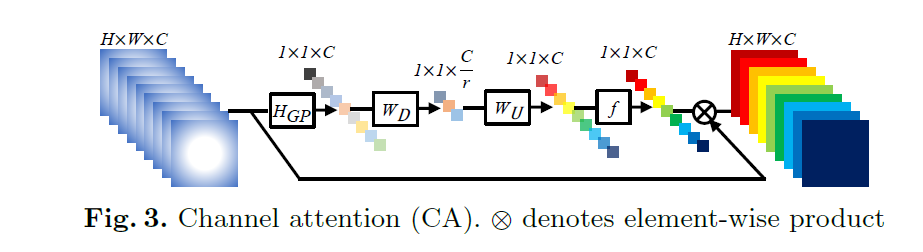
RCAB = CA + Residual Block
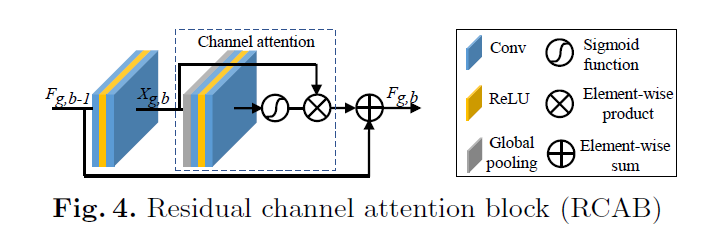
总体结构:全局残差和局部残差
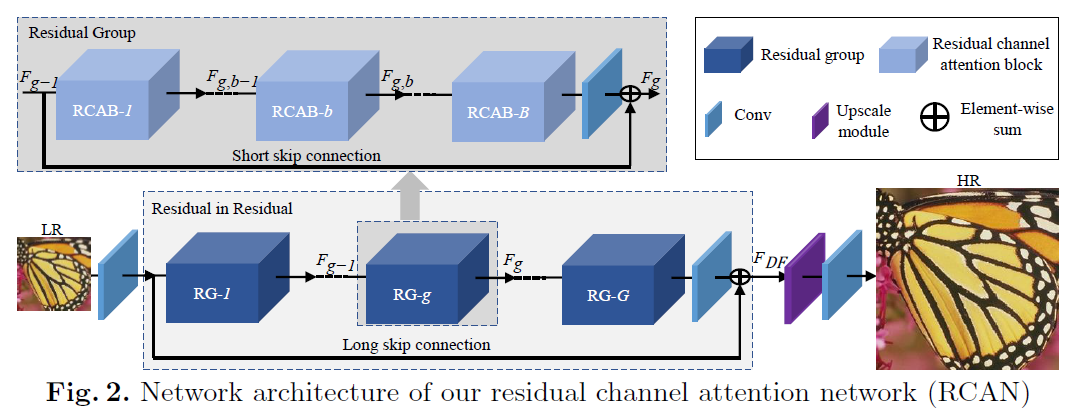
- RG数量: 10
- RCAB: 20
- number of feature map: 64
训练
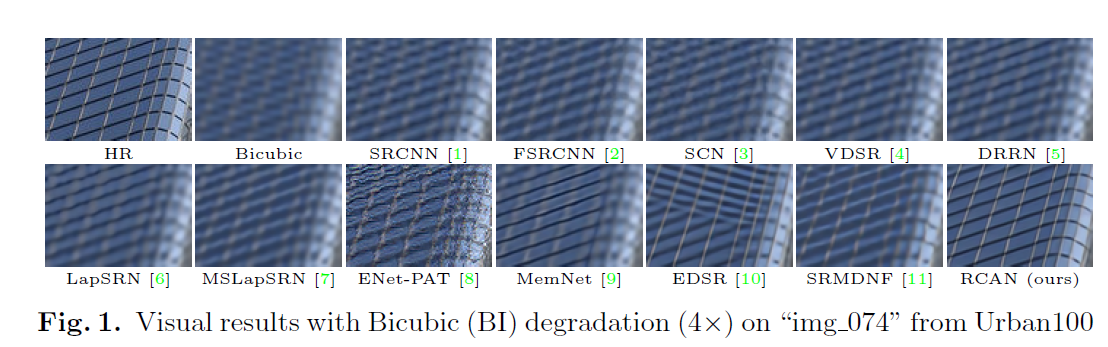
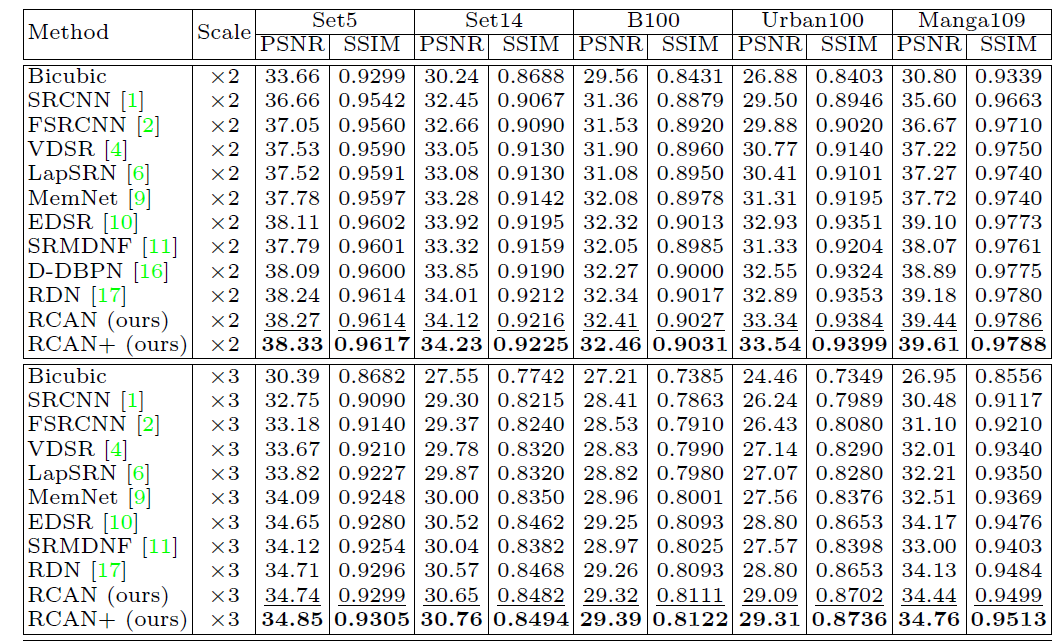
结果
SRGAN + SRResNet:Photo-realistic single image superresolution using a generative adversarial network
意图
-
how do we recover the finer texture details when we super-resolve at large upscaling factors?
-
亮点
- perceptual loss function
- GAN
网络结构设计
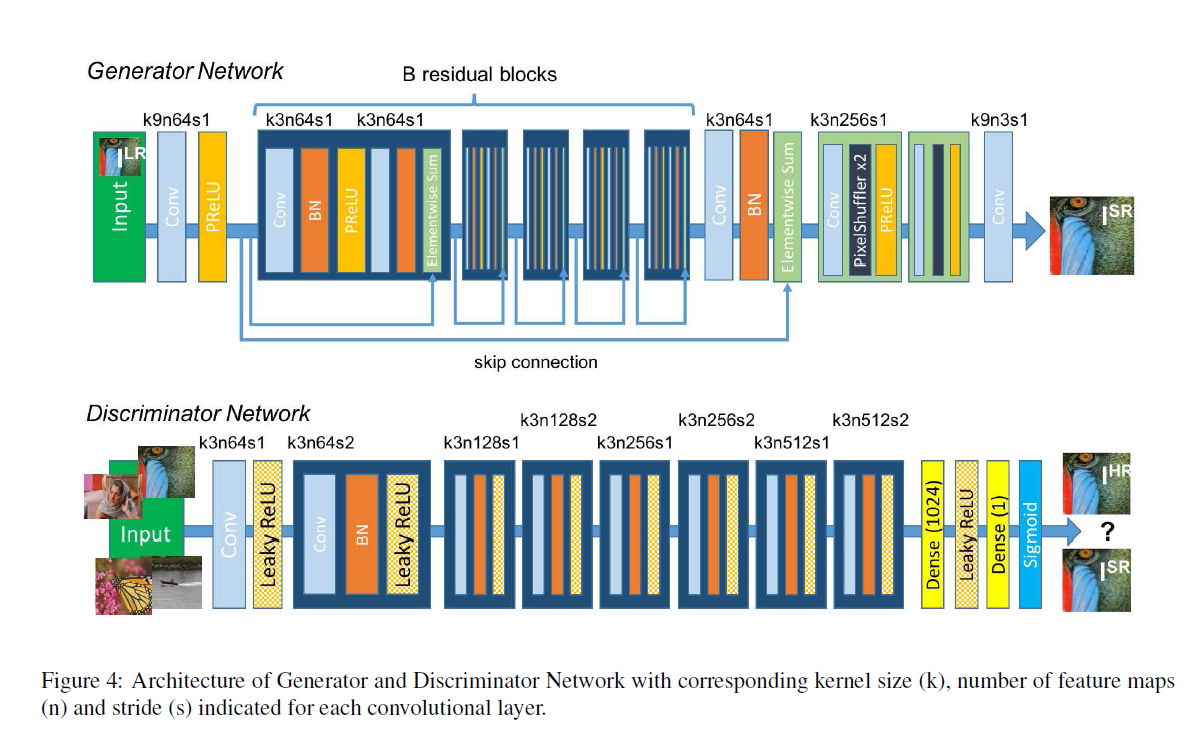
从上可知网络分为生成网络(SRRestnet) 和判别网络, 各个参数在图中有清晰的标明。生成网络(SRRestnet)采用的是残差模式,残差模块B=16
perceptual loss function
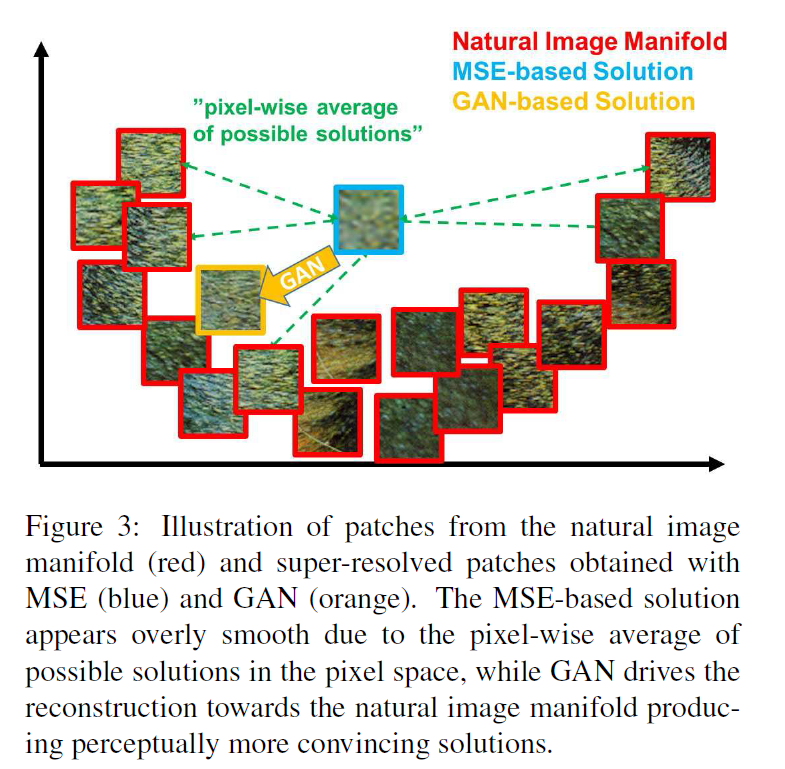
最小化基于MSE的loss, 鼓励像素的均值化,导致平滑模糊,缺少感知质量。
perceptual loss function 包含内容loss和对抗loss
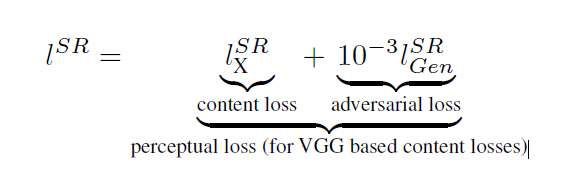
-
内容loss MSE loss
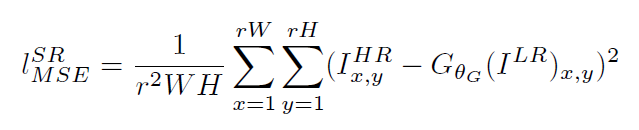
内容VGG loss:VGG 19 特征层的MSE loss
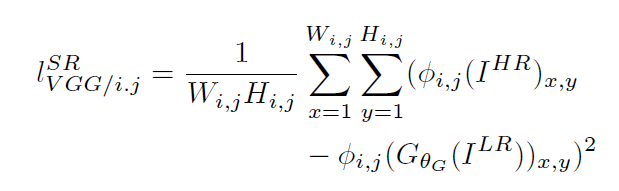
-
对抗loss 对抗loss就是正常的对抗网络的loss
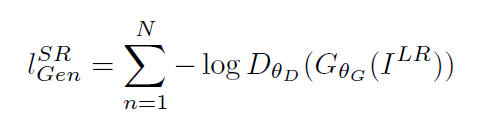
训练
- 训练数据:350 thousand images from ImageNet
- batch size : 16
- input size: HR(9696) LR(2424)
- Adam: 0.9
- SRResnet: lr 1e-4, 1e6 更新一次 1e-5
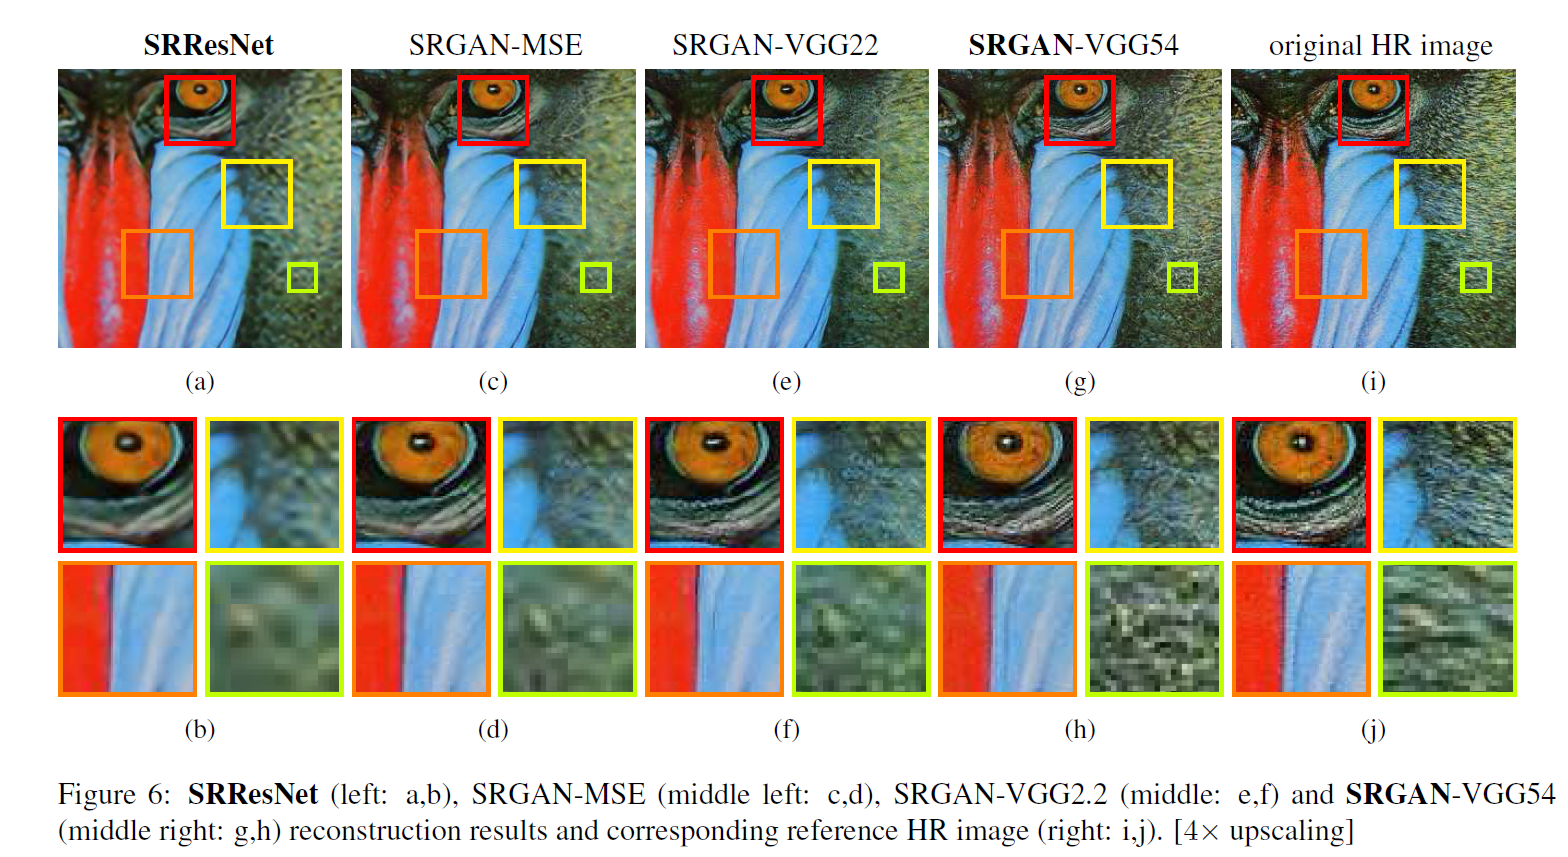
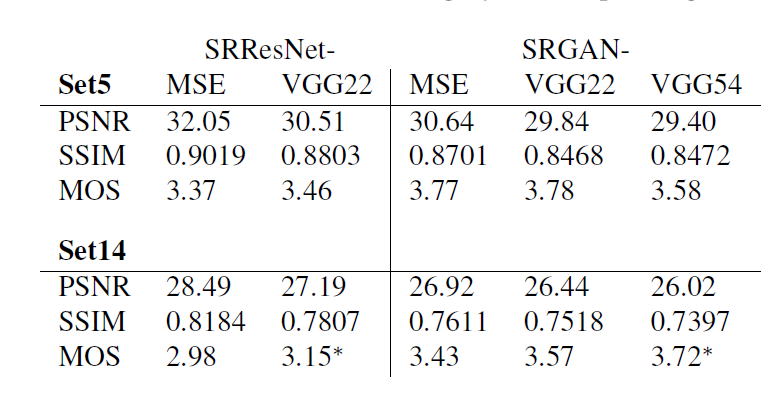
- loss:选择不同的loss(mse,感知loss(vgg 不同层vgg22, vgg54)
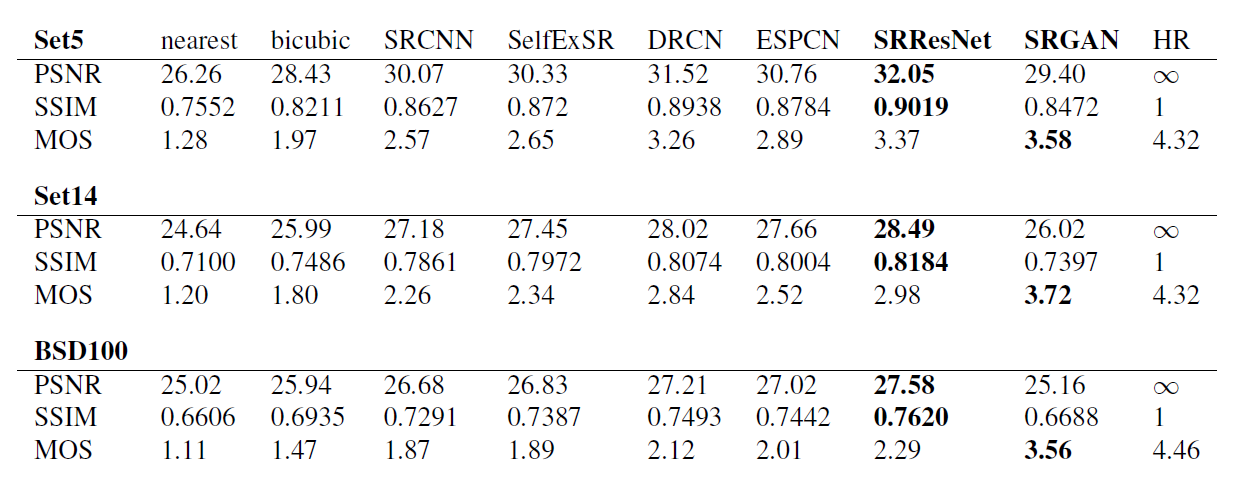
结果
PSNR不能是唯一标准,PSNR高画面质量人为感知不一定好。